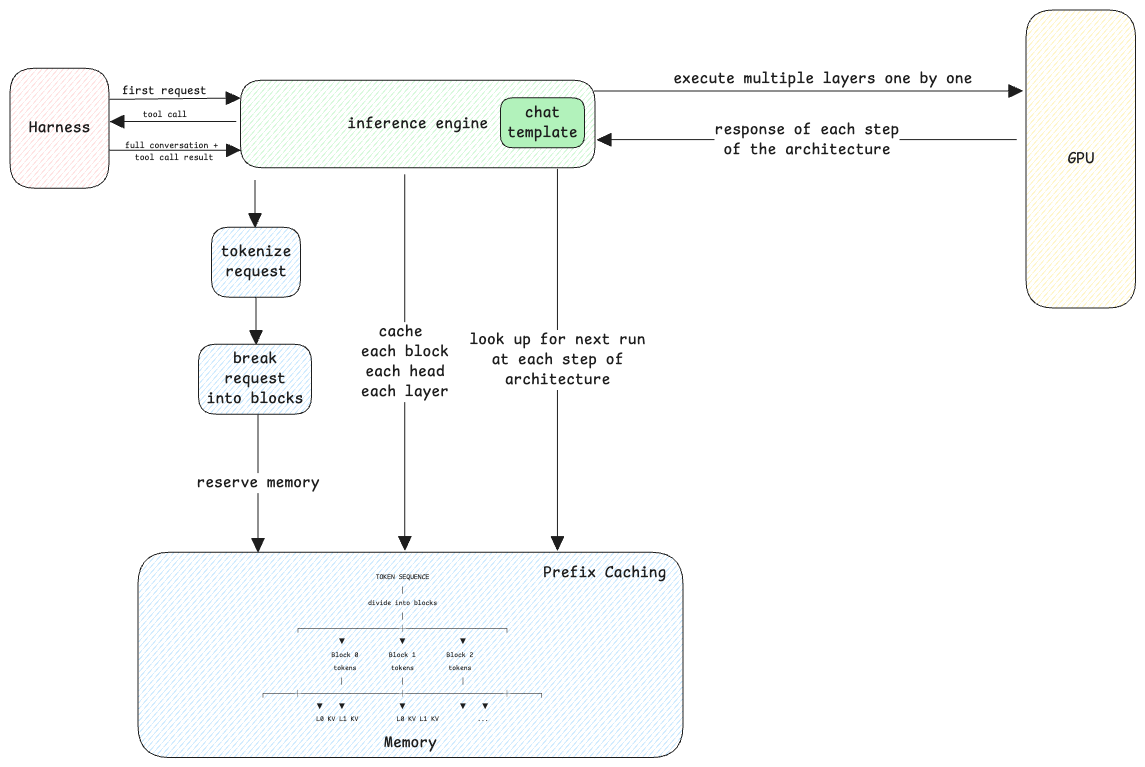
K V Cache
The LLM models have no idea about K V Cache. It's completely an inference engine implementation.
KV cache is about caching the K and V generated values to avoid performing matrix multiplications during generation of next tokens.
The name is just for usability. It refers to K-Cache and V-Cache.
To generate the next token, the transformer only uses K from all previous token to multiply with Q of the current token and at the end, it uses V from all tokens to get it's new embedding.
The K of the current token is added to the K-cache, and this new K matrix is then multiplied with single row Q matrix of the current token.

Prefix Caching
Prefix caching is a feature where the caching is done by breaking the context into smaller blocks. When a new request comes in, the request context is broken into the blocks of same size. The inference engine then tries to look up in the cache, if KV cache exists for this specific block.
A KV Cache entry is added for one specific input text block for each attention with a layer and also for multiple layers.
It's also possible that an inference engine can share the same KV cache across multiple requests. The inference engine uses prefix caching feature to find blocks that are already available and cache it.