LoRA
LoRA means Low Rank Adapter. It's a fine-tuning technique for large language models. The biggest advantage is that it uses a small number of parameters to store the fine-tuned weights.
what's low rank?
It's a matrix multiplication concept. Read more about matrix ranks here.
Low rank in LoRA means, a matrix with a lower rank is used to store weights. It uses a matrix multiplication trick by compressing first into smaller dimension and then expanding into the actual dimension needed.
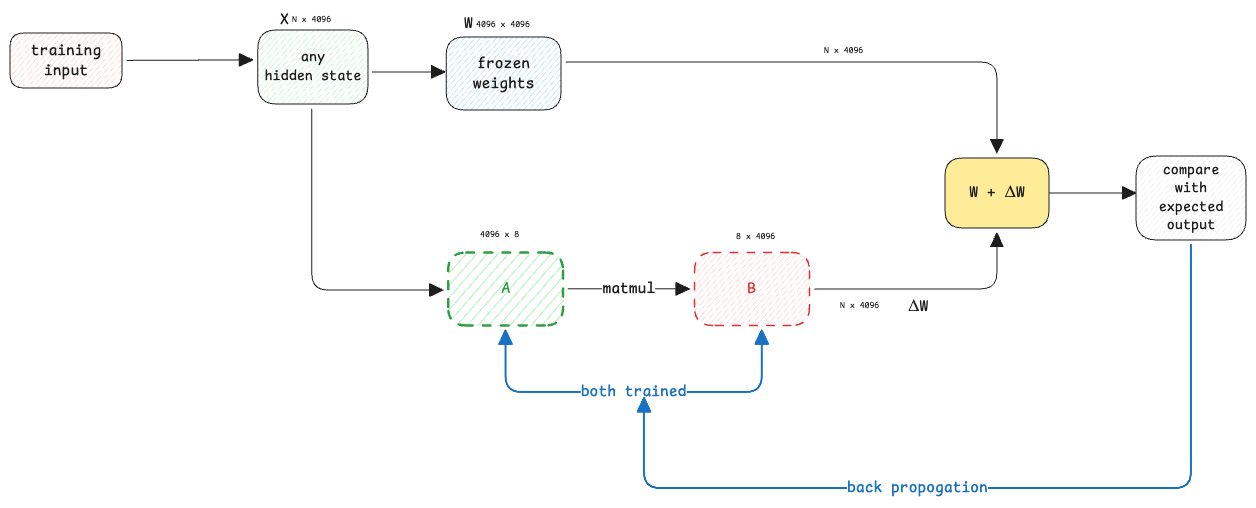
Using delta weights in inference
- The delta weights can already be added to the base model weights as a one-time operation.
- Or the addition can be performed as an additional step by the inference engine.